Tag: game servers

  • DDoS Defence by Bottleneck: A Practical Guide for Websites and Game Servers

    DDoS Defence by Bottleneck: A Practical Guide for Websites and Game Servers

    Reviewed: 13 September 2026 · Next review: 13 December 2026
    Author: Ozlin Info Editorial Team · Human review: Lin (accountable human); Codex assisted

    A DDoS plan is only useful when it names the resource that is expected to fail first. “We have a firewall” does not answer whether an incident will fill the upstream link, exhaust packet forwarding, consume connection state, overload a query parser or make the application perform too much work.

    This guide offers a defensive planning model for public websites, Java multiplayer services and Valve-family dedicated-server queries. It avoids universal thresholds and packet recipes. The goal is to help owners ask better questions, place controls in the right part of the path and define a degraded mode before an incident.

    No single control guarantees availability. Capacity, provider routing, protocol support, application design and incident response all matter. Validate any design against your provider, software versions, traffic patterns and risk appetite.

    Start with the bottleneck, not the attack name

    Use more than one traffic measure. Each describes a different kind of pressure:

    MeasureWhat it representsTypical failure point
    bps / GbpsBits carried per secondInternet circuit, transit or scrubbing capacity
    pps / MppsPackets processed per second; Mpps means millions of packets per secondRouter, NIC, virtual switch, ACL or kernel packet path
    CPSNew connections per secondSYN handling, state tables, TLS handshakes or accept queues
    Concurrent connectionsConnections held open at onceMemory, descriptors, proxy workers or load-balancer state
    RPSHTTP requests per secondReverse proxy, application, cache or database
    QPSProtocol queries per secondDNS or game-query parsing and response work

    “Bpps” can mean billions of packets per second in some network discussions, but the notation is easy to confuse with bits per second. Write out the unit in procurement and incident records.

    Average packet size can be estimated for context as bits per second ÷ (8 × packets per second). For example, 100 Gbps divided by 100 million packets per second is about 125 bytes per packet. That is illustrative arithmetic, not an attack fingerprint or a sizing promise.
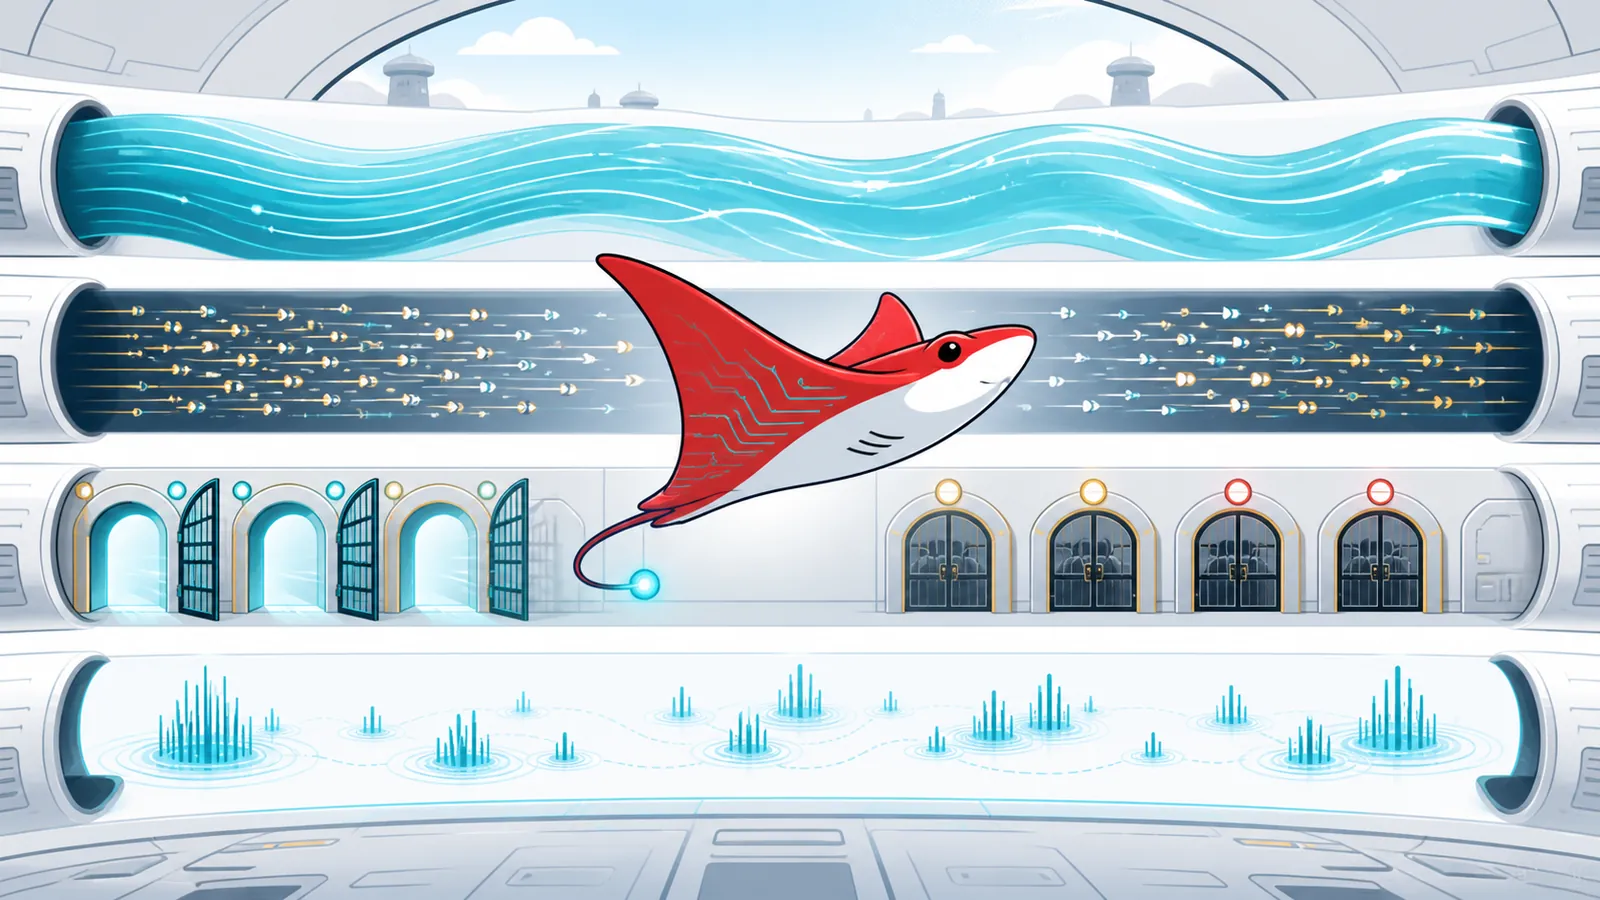
    Current Ray moves between four visual channels representing bandwidth, packet rate, connection pressure and request or query load.
    Different traffic measures reveal different bottlenecks; use shape, density and path behaviour as well as volume.

    Five useful pressure classes

    1. Volumetric pressure consumes link capacity. If the link is full before traffic reaches your server, a host firewall behind that link cannot restore the lost bandwidth. Mitigation must happen upstream, such as at the provider edge, an anycast network or a scrubbing service.
    2. Packet-rate pressure uses many small packets to exhaust packet handling before bandwidth looks full. Ask providers about packet rate as well as Gbps.
    3. Connection or state pressure targets new-connection handling or retained state. SYN defences, connection proxies and careful timeout policies help, but must be placed where they can still receive traffic.
    4. Protocol-query pressure repeatedly invokes a public protocol function, such as a status or server-browser query. It needs protocol-aware validation and budgets, not only generic port filtering.
    5. Application-resource pressure makes apparently valid requests consume CPU, database, cache, search, authentication or external-service capacity. This is commonly called application-layer or Layer 7 DDoS. “CC attack” is an informal term often used for HTTP request floods; it is not a standards-defined category.

    RFC 4732 explains why Internet denial-of-service defence is a system problem rather than a single appliance feature. BCP 38 / RFC 2827 and its update, RFC 3704, describe source-address filtering that can reduce spoofed traffic near its source. They do not stop attacks sent from valid source addresses.

    Websites: defend the whole request path

    A useful website pattern is:

    upstream or anycast edge → HTTP DDoS controls → validation and WAF → cache → reverse proxy → bounded application and queue → origin data stores

    • Upstream or edge capacity absorbs traffic before the origin link becomes the bottleneck.
    • Request validation and WAF rules reject traffic that violates known application behaviour.
    • Caching prevents repeated public reads from becoming repeated origin work.
    • Path-specific budgets recognise that a cached article, a login, a search and a large export have very different costs.
    • Queues and back-pressure keep a burst from turning into uncontrolled work.
    • Graceful degradation preserves essential pages while temporarily disabling expensive search, exports, previews or third-party calls.
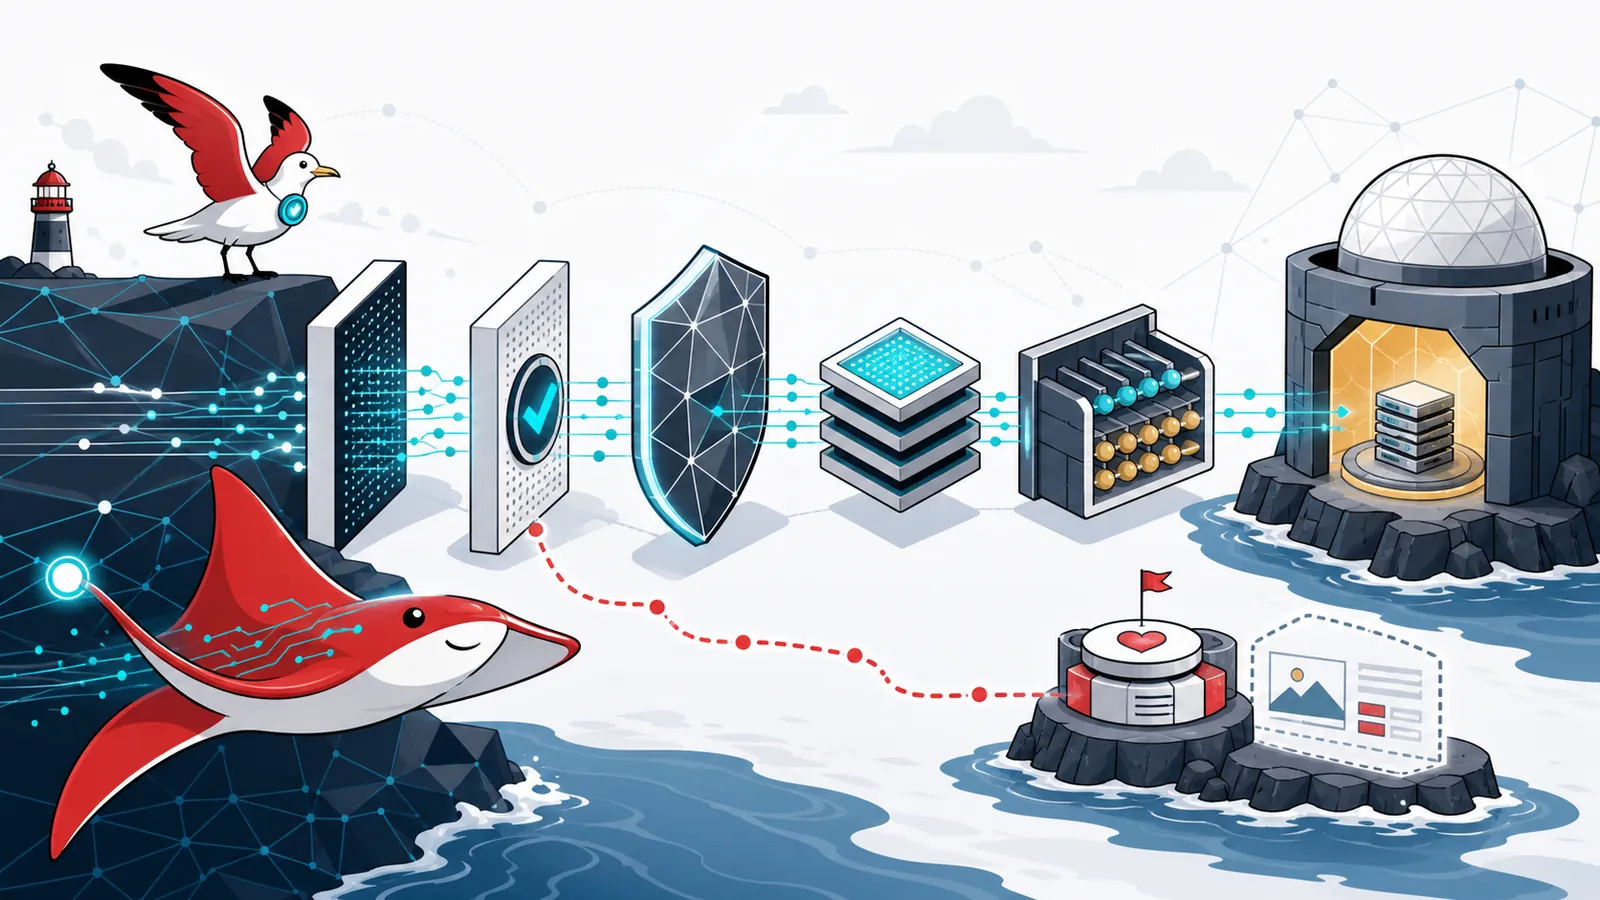
    Current Ray and Signal Gull guide website traffic through validation, a shield, cache, queue, protected origin and a separate degraded-service path.
    Website resilience depends on layers that reduce work before traffic reaches the origin.

    Conceal and constrain the origin

    An HTTP reverse proxy is bypassable if the origin address remains reachable. Cloudflare’s own guidance recommends proxying appropriate DNS records, auditing DNS-only records for origin exposure, restricting origin access and rotating an address that has previously been exposed. Those are Cloudflare-specific operational recommendations; equivalent controls differ by provider.

    Do not assume that an ordinary HTTP CDN or proxied DNS record protects arbitrary raw game protocols. Cloudflare documents that proxied DNS covers specific HTTP/HTTPS ports, while other TCP/UDP services need a protocol-specific product or upstream service. Confirm the clean traffic path before changing DNS.

    Rate limits need context

    Per-address limits are simple, but mobile carriers, offices, universities and households may share public addresses through NAT or CGNAT. A rigid source-IP threshold can punish legitimate users. Combine signals where the platform permits it: path, method, session, authenticated identity, token, device evidence, request cost and behaviour over time. Maintain a documented false-positive appeal or bypass process.

    Cloudflare recommends combining managed DDoS controls, custom WAF rules, rate limits, origin protection and caching. Treat that as vendor guidance, then test it against your actual application and plan level. Rate limits are especially useful when they describe the expensive route they protect rather than applying one blanket number to every request.

    Java multiplayer services: separate status, login and play

    • Status discovery supports server-list visibility and should be lightweight and observable.
    • Login and authentication create new connection, cryptographic and identity work.
    • Join and initialisation load player data, plugins, worlds or resource checks.
    • Ongoing play produces long-lived, stateful traffic with game-specific packet handling.

    A protocol-aware edge can distinguish these stages and protect a proxy tier. A common architecture is a protected public edge, a Velocity proxy and isolated backend servers that accept connections only from the trusted proxy path.
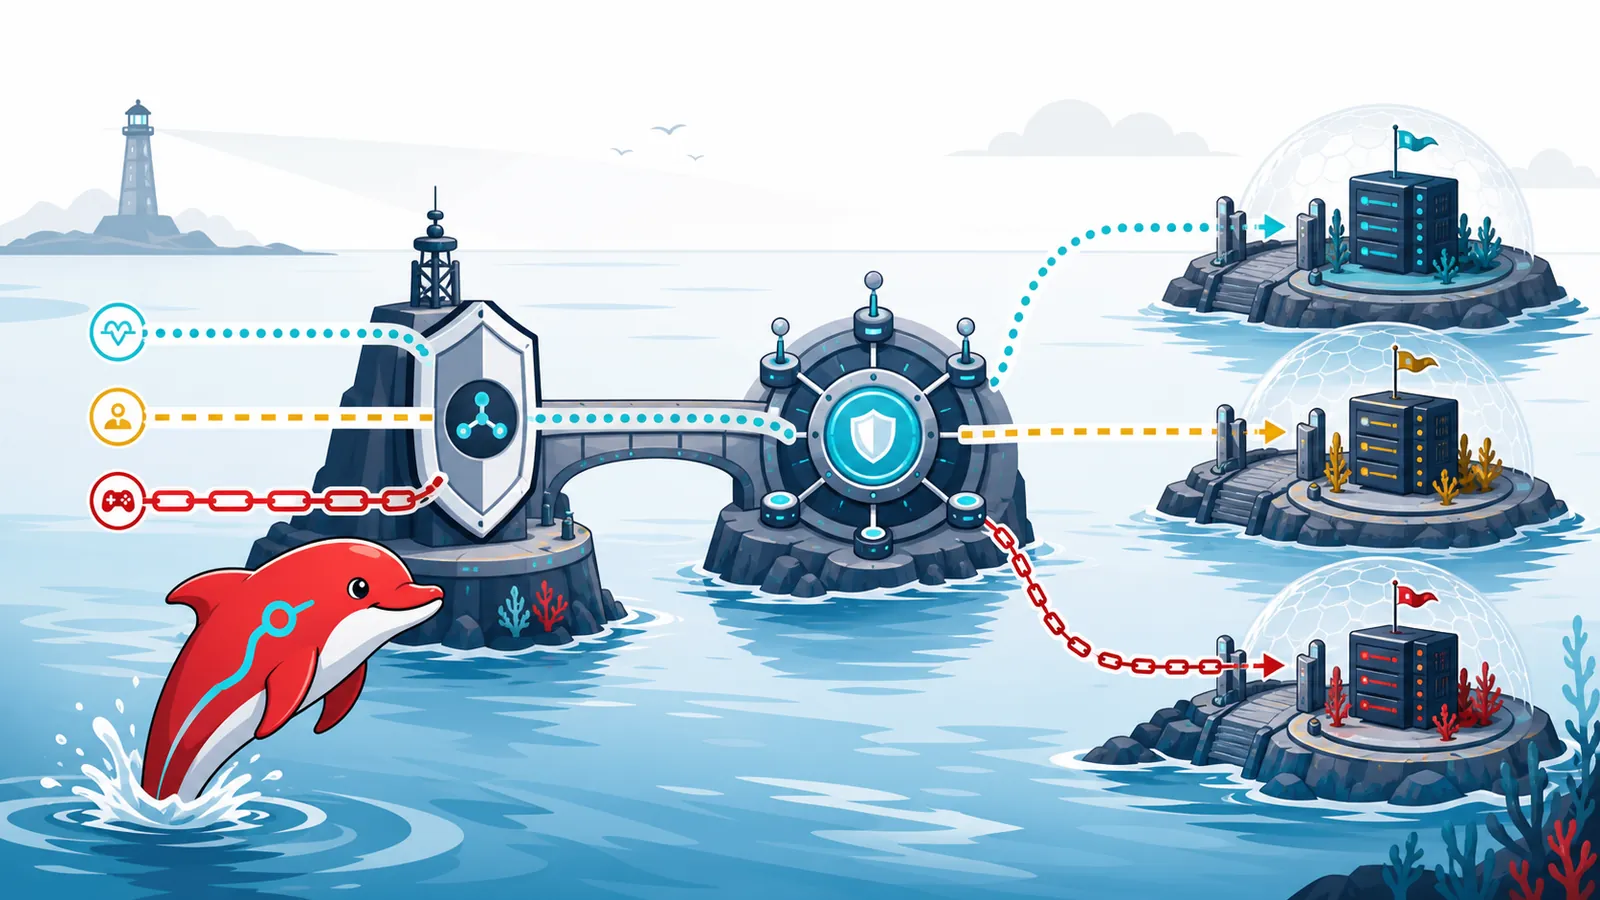
    Harbour Dolphin maps three distinct Java multiplayer traffic paths through a protected proxy hub to isolated backend server nodes.
    Separate status, login and play paths so controls reflect their different costs and user impact.

    PaperMC’s current Velocity security documentation strongly recommends a firewall for backend isolation. It also warns that Velocity modern forwarding is a second layer of protection, not a replacement for a firewall. Keep the proxy and backend software updated, restrict backend reachability and review plugins because application-level abuse can still consume server work after network traffic is accepted.

    Do not copy a universal join-rate or packet threshold from a blog. Establish a legitimate baseline, test player experience, change one control at a time and keep an emergency rollback. A protection provider should be able to explain whether it understands the game protocol or merely forwards a protected generic TCP stream.

    Valve-family server queries: challenge spoofing, then budget real sources

    Valve-family dedicated servers expose discovery information through A2S query types commonly known as A2S_INFO, A2S_PLAYER and A2S_RULES. These queries are useful to players and server browsers, but unauthenticated UDP responses can contribute to reflection risk when source addresses are spoofed. High query rates from real sources can also consume packet and protocol-processing capacity.

    Valve developer communication describes an A2S challenge exchange that lets a server ask a client to return a challenge before an information response, helping demonstrate that the requester can receive traffic at the claimed source. That can reduce spoofed reflection. It cannot prove that a real-source bot is benign, and it does not create infinite query capacity.
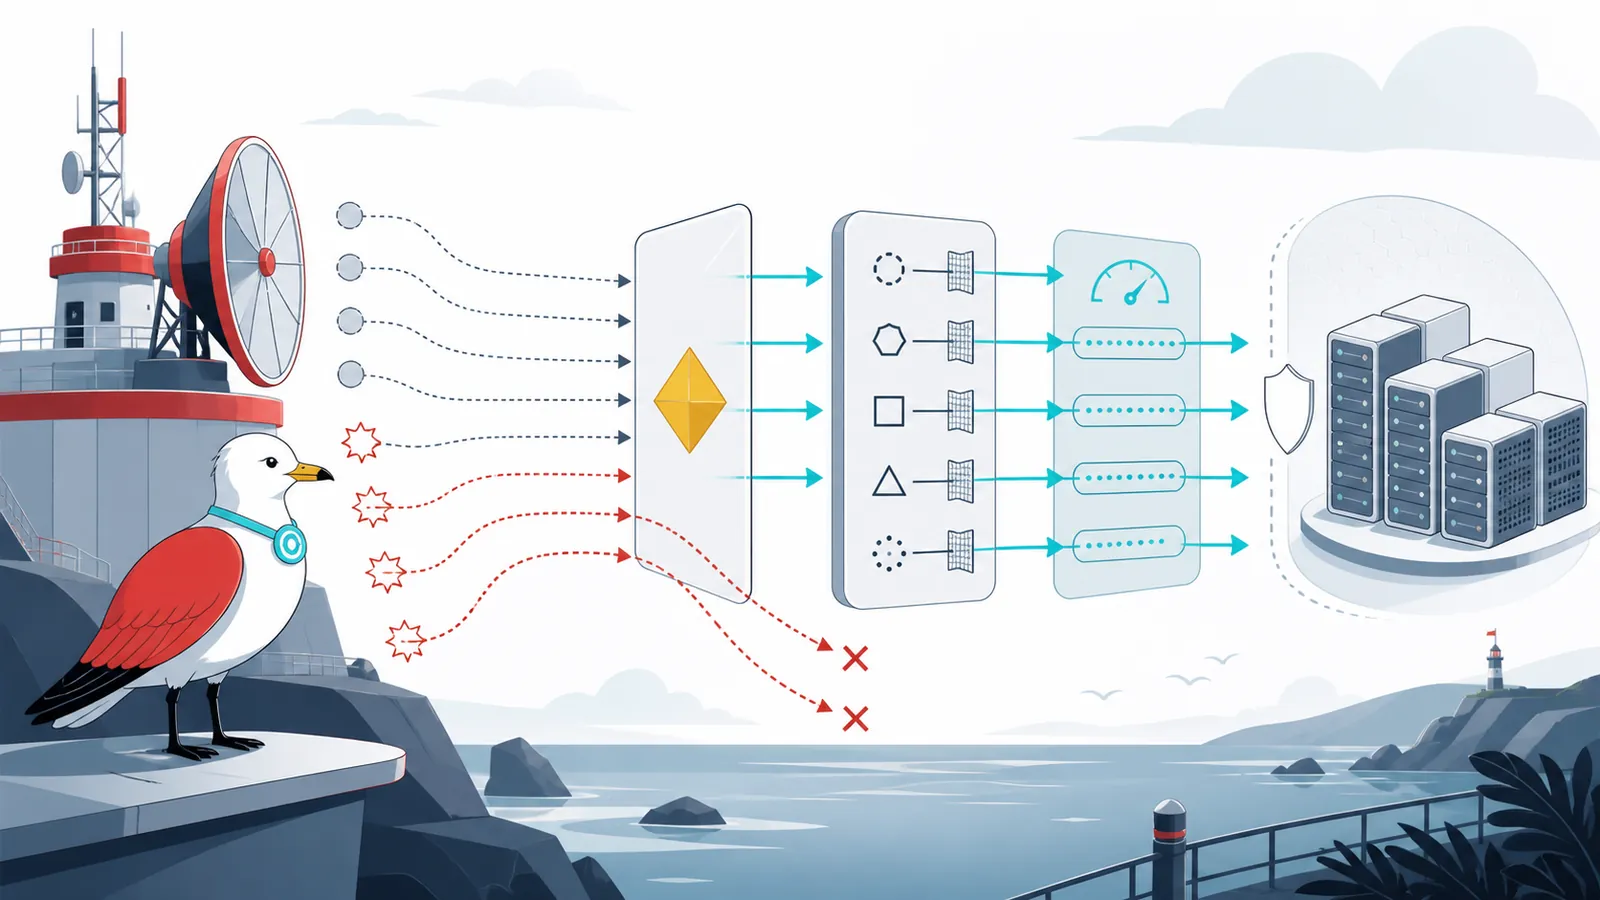
    Signal Gull observes geometric query challenges, protocol-aware filters and rate-controlled paths protecting a generic dedicated-server cluster.
    Challenge validation addresses spoofing; protocol-aware budgets and monitoring still matter for real-source query floods.
    • current server software and protocol support;
    • challenge validation where compatible;
    • protocol-aware filtering before expensive parsing;
    • separate budgets and observability for information, player and rules queries;
    • aggregate and source-aware controls that do not rely on one address threshold alone;
    • an incident mode that preserves the minimum discovery response needed for legitimate clients, if the game and provider support it.

    The Steamworks game-server overview explains the role of game-server discovery and connection. The challenge details above are based on a Valve developer-authored Steam Community announcement, not an RFC; compatibility and defaults can change, so verify them against the current game build and hosting provider.

    What to ask a DDoS provider

    • What clean and attack capacity is stated in Gbps and packets per second?
    • How are new connections, simultaneous state and protocol queries handled?
    • Which of our actual protocols are parsed, proxied or merely forwarded?
    • Is mitigation always on or triggered on demand, and what is the expected time to mitigate?
    • Where does clean traffic re-enter our network, and what latency or MTU changes should we expect?
    • What traffic and mitigation telemetry can we access during and after an event?
    • What is the escalation path, including after-hours response?
    • How are legitimate-traffic drops investigated and corrected?
    • Which features, traffic volumes, logs, support levels or data transfers add cost?
    • What happens if the origin address is exposed or attacked directly?

    OVHcloud’s Network Security Dashboard documentation is a useful example of provider-side visibility: it describes per-address events, attack-vector labels, bps/pps charts, clean and dropped traffic, and escalation data. Those fields describe one provider’s service, not a universal capability. Record what your selected provider actually offers.

    A compact incident and degradation runbook

    1. Declare and timestamp. Nominate an incident lead, start a record and preserve provider alerts and dashboards.
    2. Classify the bottleneck. Compare link utilisation, pps, new connections, concurrent state, request/query rates, latency, errors, queue depth and host saturation.
    3. Protect the management path. Keep administrative access separate where practical; avoid making emergency changes through the affected public service.
    4. Escalate upstream early. If the link or provider edge is the bottleneck, contact the network or mitigation provider with destination, protocol, time window, customer impact and evidence.
    5. Apply the smallest prepared control. Use reviewed edge rules, path budgets or protocol policies. Record the owner, timestamp and rollback.
    6. Degrade intentionally. Serve cached or static content, pause expensive routes, reduce optional query detail or limit new joins while preserving existing sessions where feasible.
    7. Watch legitimate traffic. Sample successful user journeys, geographic reachability, authentication and game-session health. Roll back a control that causes disproportionate harm.
    8. Recover and review. Remove temporary controls carefully, retain evidence according to policy, document false positives and update the capacity model.

    Monitoring signals worth keeping together

    • provider and interface bps/pps;
    • packet drops and NIC, virtual-switch or kernel saturation;
    • SYN rate, accepted connections, resets, timeouts and connection occupancy;
    • edge, cache and origin request rates plus cache-hit ratio;
    • application latency, error rate, worker saturation, queue depth and database pressure;
    • status, login, join, play and query-path health for game services;
    • clean-traffic delivery, mitigation start/stop times and false positives;
    • customer-impact signals such as successful page journeys or completed joins.

    Alerts should identify the suspected bottleneck and a human owner, not merely announce “high traffic”.

    Limits of this guide

    This is general educational information, not a guarantee, penetration-test instruction or substitute for provider engineering. It does not prescribe universal capacity, thresholds or packet filters. Service architecture, versions, jurisdiction, budget and acceptable user impact can change the correct design. Test controls in an authorised environment, maintain rollback and confirm contractual limits directly with suppliers.

    Plan the failure path before buying capacity

    DDoS resilience improves when owners can answer three questions: what resource fails first, who can act before that point, and what essential service remains during degradation? That model turns product names into testable requirements and makes incident decisions faster.

    If you need a bounded review of public exposure, dependencies, monitoring and recovery priorities, see Ozlin Info’s Cybersecurity Risk Advisory or contact us. Related reading: Incident Response and Disaster Recovery Planning and Home Broadband Server Hosting Risks in Australia.


    Sources and review note

    Material technical claims were checked on 31 August 2026 against the RFC Editor, Cloudflare documentation, PaperMC Velocity documentation, Steamworks documentation, a labelled Valve developer communication and OVHcloud documentation. Product behaviour and documentation can change; next scheduled review is 28 February 2027.

    AI disclosure: AI assisted with source discovery, drafting, copyediting and the original editorial illustrations; Ozlin Info reviewed the final article and remains responsible for publication.

    Source access date: 2026-08-29

    Limitations: DDoS controls, capacity, routes, protocol support, provider terms and application behaviour vary by environment and can change; validate the intended design with measured, authorised tests.
  • How to Size a Game Server in Australia: Minecraft, Counter-Strike and Hosting Models

    How to Size a Game Server in Australia: Minecraft, Counter-Strike and Hosting Models

    Reviewed: 13 September 2026 · Next review: 13 December 2026
    Author: Ozlin Info Editorial Team · Human review: Lin (accountable human); Codex assisted

    Player slots are a sales unit, not a hardware specification. A quiet 64-slot server and a full 64-player modded event can have completely different CPU, memory and network demands. Minecraft chunk generation, a Counter-Strike map plugin, bots, database calls and downloads all change the workload. Australian and New Zealand players then add geography, ISP routing, traffic quotas and attack exposure to the calculation.

    The defensible method is to choose a starting configuration, run the real server build, collect tick and network measurements under representative concurrency, and adjust. This article's configurations are Ozlin starting test baselines, not performance guarantees.

    Ozlin also brings direct operational context: on one 64-player Counter-Strike 2 zombie-escape environment, Ozlin has observed outbound traffic peak at roughly 150 Mbps. That is a field observation for that map/plugin/player mix, not a universal 64-slot requirement. Ozlin has also found Zriot-style zombie-bot workloads materially CPU-intensive on the server. Human slots and bot count must therefore be tested as separate load dimensions.

    Define the workload before assigning cores

    Capture more than the maximum player count:

    • typical, planned-event and maximum concurrent users (CCU);
    • game and exact server build;
    • tick or simulation target;
    • maps, world size, view/simulation distance and chunk-generation plan;
    • plugins, mods, scripting runtimes and databases;
    • bot type and count;
    • voice, replay, anti-cheat and logging;
    • FastDL, Workshop or mod-distribution method;
    • backup size, frequency and restore objective;
    • expected player cities and ISPs; and
    • DDoS exposure, community visibility and moderation model.

    Measure the busy period, not a fresh empty server. Retain a reproducible test world/map and plugin set so an upgrade can be compared with the previous build.

    Minecraft starting test profiles

    Paper's troubleshooting guidance emphasises strong single-thread performance and recommends at least four threads, while its bundled spark profiler helps find tick problems. More cores do not automatically repair one overloaded main thread. World generation, entities, hoppers, redstone, view distance and plugins can dominate.

    Planned Java/Paper CCU Ozlin starting CPU baseline Starting memory Commissioning focus
    5–10 4 modern high-speed threads 4–6 GB Java heap; about 8 GB system total Pregenerate nearby world, cap view/simulation distance, profile plugins
    20–40 4–6 modern high-speed threads 8–12 GB heap; about 16 GB system total Test exploration, farms, backups and database activity at once
    50–100 6–8+ high-speed threads 12–24 GB heap; about 32 GB system total Pregeneration, entity controls, profiling, tuned proxy/sharding decisions and load rehearsal

    These are not minimum requirements published by Mojang or Paper. They are starting points for a controlled test. Avoid assigning an enormous heap “just in case”: garbage collection and memory pressure can worsen pauses. Leave memory for the operating system, filesystem cache, panel agent, backup and database. Use supported Java versions and current Paper documentation for the selected game build.

    Run spark or the documented profiler during a real busy period. Watch mean tick time and long-tail stalls, not only average CPU percentage. A 25% total CPU graph on a four-core VM can conceal one saturated main thread. Record chunk generation, entity and plugin contributors before buying more RAM.

    Counter-Strike 2 starting test profiles

    Counter-Strike server behaviour depends on tick processing, map, player count, plugins, bots and networking. Valve's developer wiki describes CS2's 64-tick/subtick networking at a high level, but community documentation and the game itself evolve; validate the current dedicated-server build.

    Planned slots Ozlin starting CPU baseline Starting memory Commissioning focus
    12–24 4 modern high-speed cores About 8 GB system RAM Stable frame/tick processing, map change, logging, plugins and peak packets
    32–64 6–8 modern high-speed cores About 16 GB system RAM Full-player rehearsal, complex maps, plugins, database calls and sustained network capture
    32–64 with heavy zombie mode or many bots Begin above the corresponding human profile and reserve dedicated CPU headroom 16 GB+ depending on plugins/assets Test bot count, AI update cost, map and human CCU independently; profile server frame time

    Do not size a Zriot zombie-bot server by human slots alone. Bots perform server-side decision and movement work; adding twenty bots can change CPU demand even if no additional internet client joins. Create a test matrix such as 0/10/20/40 bots crossed with low and high human CCU. Capture server-frame or tick health, the busiest core, plugin timings and network output. Reduce or reschedule expensive bot logic before assuming that more vCPUs will help.

    Zombie escape creates another special case. Large maps, many moving entities, custom effects and mass player movement can cause bursty updates. Ozlin's approximately 150 Mbps observed peak means a 100 Mbps port would not provide enough instantaneous capacity for that environment. A 1 Gbps port creates headroom, but its existence says nothing about the monthly transfer quota, congestion, provider shaping or route quality.

    Calculate transfer from a measured rate

    For decimal terabytes of one-direction traffic:

    TB ≈ Mbps × active hours × 0.00045

    This follows from megabits per second × seconds ÷ eight, using decimal units. One continuous 1 Mbps stream for 30 days is about 0.324 TB.

    Use a representative average or p95 over the defined active window, not the single highest graph spike. For example, if measurements—not a guess—show 65 Mbps p95 during six busy hours per day across 30 days, the planning value is:

    65 × 180 × 0.00045 ≈ 5.27 TB outbound

    If the service really sustained 150 Mbps for those same 180 hours, it would be about 12.15 TB. Ozlin's 150 Mbps value is a peak observation, so applying it as a month-long average would overstate ordinary transfer. Add inbound traffic, updates, backups, FastDL and monitoring separately, then apply a growth and incident margin.

    For a provider advertising “15 TB on a 10 Gbps port”, 10 Gbps describes possible port rate while 15 TB describes allowed transfer under the contract. For “1 Gbps unmetered”, inspect fair-use and shaping language. A traffic quota, port speed, latency, jitter, loss and DDoS mitigation are six distinct properties.

    Not all Australian server products are traffic-capped. Some publish quotas, some advertise unmetered service, and public cloud commonly meters egress. Compare the exact product and location. The Australia and New Zealand hosting guide provides a broader provider matrix.

    Test routes from players, not from the administrator's desk

    Measure round-trip latency, jitter and loss from the cities and access networks where players actually live. A Sydney server may be excellent for east-coast users and suboptimal for Perth or New Zealand depending on routing. An Auckland or Perth deployment can improve a local audience without improving every international path.

    Run tests at evening peak and during events. Capture route changes and loss over time. A low average ping with periodic loss can feel worse than a slightly higher stable ping. Avoid relying on ICMP alone if a network deprioritises it; combine it with application telemetry and player reports.

    DDoS protection deserves explicit questions: which game and transport protocols are covered, whether mitigation is always-on, how false positives are handled, what happens above plan limits, whether application-layer floods are included, and how support escalates an incident. No provider protection makes an unpatched game server safe.

    Slots hosting, VPS, dedicated or colocation?

    Pay-by-slots game hosting

    This is suitable when a community wants a managed game instance without owning the operating system. A provider may expose TCAdmin, Pterodactyl or another panel for configuration, scheduled tasks and backups. Advantages include fast setup, game-aware support and no host patching. Limits can include no root/SSH/RDP access, constrained plugins, shared CPU, fixed backup policies and limited network visibility.

    Ask whether CPU allocation is dedicated, what happens during noisy-neighbour load, which locations and DDoS controls apply, and whether files/data can be exported. A panel label does not reveal the underlying hardware.

    VPS

    A VPS offers root access and flexible automation at low entry cost. It suits smaller servers, test instances, proxies and supporting services. Confirm CPU scheduling, sustained clock behaviour, storage performance and traffic. A plan advertising many vCPUs can lose to fewer faster dedicated cores for a main-thread-heavy game.

    Dedicated server

    Dedicated hardware is often the practical step for large communities, multiple instances or demanding mods. It provides predictable cores, memory and local storage, but the operator owns patching, backups, monitoring, recovery and most application security. One host is still one failure domain. Keep external backups and rehearse rebuilding the service.

    Colocation

    Colocation makes sense when stable demand justifies owned hardware and someone can manage spares, firmware, remote hands, power and logistics. It is rarely the cheapest first experiment. Price rack space, power, transit, mitigation, addresses, remote hands and hardware depreciation together.

    Decision factor Slots hosting VPS Dedicated Colocation
    Root control Usually none Yes Yes Yes, including hardware
    Launch effort Lowest Moderate High Highest
    CPU predictability Provider-specific Provider-specific Stronger Strongest under your design
    Custom panels/services Limited Flexible Flexible Flexible
    Hardware responsibility Provider Provider Provider replaces under contract Customer
    Best starting use Small/standard communities Labs and moderate servers Large or multiple workloads Mature, stable operations

    TCAdmin and Pterodactyl are management layers. Pterodactyl Wings uses containers and exposes CPU/memory limits; TCAdmin can select servers and provision products by slots through billing integrations. Neither product guarantees the CPU underneath, low latency or competent backup. Read the host's allocation and support terms.

    Budget the supporting services

    Backups: Separate configuration, world/map data, databases and replaceable game binaries. Keep at least one copy outside the game host and test a restore. Snapshot-only backup on the same storage is not enough.

    Monitoring: Record service health, CPU per core, memory, disk latency/capacity, tick or frame time, player count, packet loss, traffic rate and backup status. Alerts need an owner and response procedure.

    Updates: Stage game, plugin, mod and panel updates before major events. Keep a rollback artifact and protect administrative credentials with MFA or a restricted management path where supported.

    Content distribution: Steam Workshop is the preferred distribution path where the game and content support it. FastDL may still be required for some legacy or custom-server assets; serve only intended static files, use correct MIME types, prevent script execution and monitor bandwidth. Do not expose backups, configuration or credentials through a directory lister.

    Community controls: SourceBans or equivalent systems, Discord integrations and web panels handle personal data and privileged actions. Patch them, minimise permissions, use supported software and define retention. Never deploy cracked/nulled plugins, panels or game assets: unknown code can add web shells, credential theft or botnet functionality, and copyright risk is not a technical strategy.

    Operations: Moderation, abuse handling, incident response, DDoS escalation and restore time often cost more than the VM. Include them in the hosting decision and publish separate community terms where appropriate. Ozlin's projects page describes the broader community and technical context without exposing production internals.

    Commission, measure, then scale

    1. Build the exact game, map/world, plugins and bot configuration on a test host.
    2. Generate representative load or hold a controlled event.
    3. Record per-core CPU, memory, tick/frame health, p95 and peak network, loss, disk and temperatures.
    4. Identify whether the limit is one thread, memory, storage, network rate, quota or software.
    5. Change one major variable at a time and repeat.
    6. Test backup restore, update rollback and host rebuild.
    7. Recalculate monthly transfer and 12-month TCO from measurements.
    8. Set capacity alerts below the player-visible failure point.

    The right answer may be a managed 20-slot product, a fast dedicated CPU, or several isolated instances. The evidence should show why. Ozlin's infrastructure services can help turn player goals and operational constraints into a measurable hosting plan without treating slot count as a promise.

    Limitations: Capacity and cost figures are illustrative. Actual throughput, tick rate, latency and reliability depend on the game build, mods, plugins, host CPU, neighbours, network, player behaviour, backups and current pricing; measure the intended workload.

    Sources and review record

    Sources were accessed on 29 August 2026. Game builds, panel documentation, provider terms and Ozlin measurement baselines are scheduled for review by 29 November 2026.

    AI assisted with source discovery, drafting and copyediting; Ozlin Info remains responsible for publication.

    Source access date: 2026-08-29

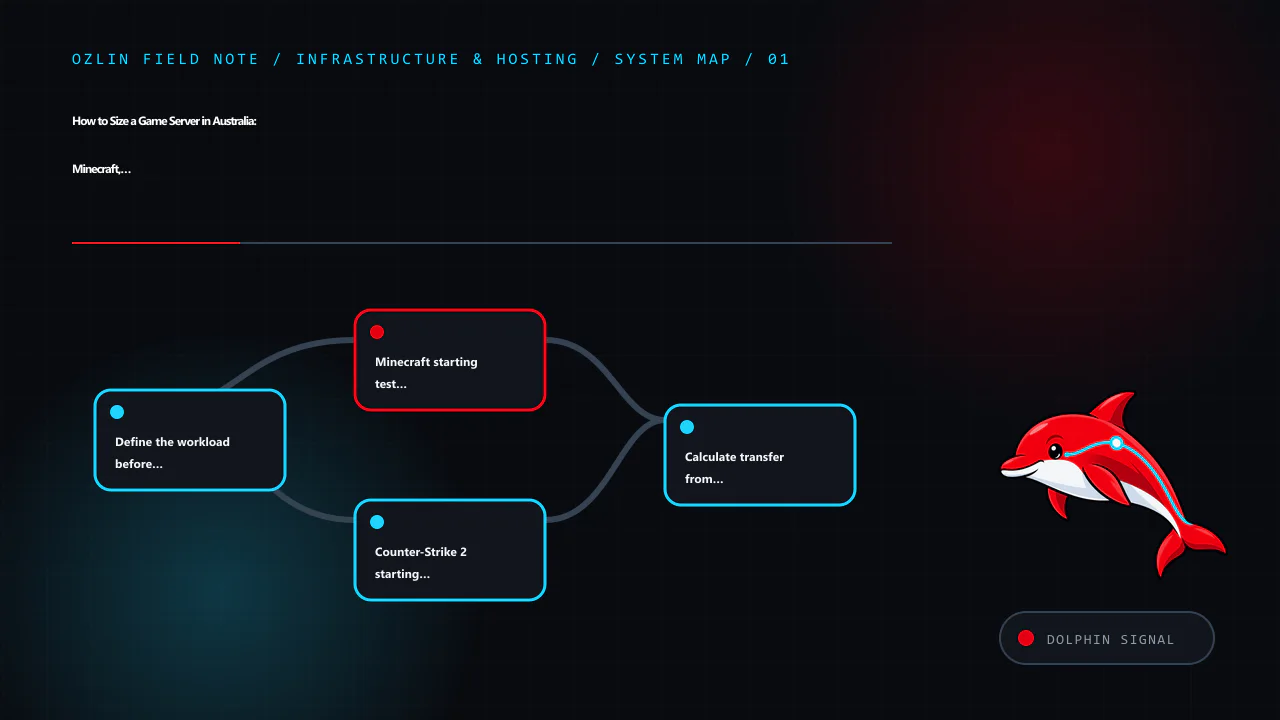
    Article map for How to Size a Game Server in Australia: Minecraft, Counter-Strike and…, covering Define the workload before assigning cores, Minecraft starting test profiles, Counter-Strike 2 starting test profiles and…
    Article map: Define the workload before assigning cores; Minecraft starting test profiles; Counter-Strike 2 starting test profiles; Calculate transfer from a measured rate.
    Decision path for How to Size a Game Server in Australia: Minecraft, Counter-Strike and…, covering Minecraft starting test profiles, Counter-Strike 2 starting test profiles, Calculate transfer from a measured rate and r…
    Decision path: Minecraft starting test profiles; Counter-Strike 2 starting test profiles; Calculate transfer from a measured rate; Test routes from players, not from the administrator's desk.
    Control and evidence map for How to Size a Game Server in Australia: Minecraft, Counter-Strike and…, covering Calculate transfer from a measured rate, Test routes from players, not from the administrator's desk, Slots h…
    Control and evidence map: Calculate transfer from a measured rate; Test routes from players, not from the administrator's desk; Slots hosting, VPS, dedicated or colocation?; Budget the supporting services.
    Practical checklist for How to Size a Game Server in Australia: Minecraft, Counter-Strike and…, covering Slots hosting, VPS, dedicated or colocation?, Budget the supporting services, Commission, measure, then scale and…
    Practical checklist: Slots hosting, VPS, dedicated or colocation?; Budget the supporting services; Commission, measure, then scale; Sources and review record.